Qwen-Image 2.1 has arrived, bringing a new 7B image-generation component, improved image editing, native transparency support, and support for up to 10 reference images.
If you’re thinking about purchasing a new GPU, we’d greatly appreciate it if you used our Amazon Associate links. The price you pay will be exactly the same, but Amazon provides us with a small commission for each purchase. It’s a simple way to support our site and helps us keep creating useful content for you. Recommended GPUs: RTX 5090, RTX 5080, and RTX 5070. #ad
Qwen also released native ComfyUI support alongside the model. If you have enough VRAM, you can run the original BF16 or INT8 versions. However, if you want to reduce memory usage, several GGUF versions are now available from the community.
In this guide, I’ll show you how to run Qwen-Image 2.1 GGUF in ComfyUI using the Qwen-specific quantizations from RealRebelAI.
What Is Qwen-Image 2.1?
Qwen-Image 2.1 is the latest image-generation model from Qwen. Unlike a separate image-generation and image-editing model workflow, Qwen-Image 2.1 combines generation and editing capabilities into one model.
The visual generation component has 7 billion parameters and uses 32 Single-Stream DiT layers.
Some of the major improvements in Qwen-Image 2.1 include:
- Text-to-image generation
- Image editing
- Native transparent image generation
- Transparent image editing
- Up to 10 reference images
- Local editing using masks and annotations
- Improved text rendering
- Improved portrait lighting and fine details
- Better preservation of people and products during editing
The model can also use multiple reference images to create a single composition. For example, Qwen demonstrates combining multiple people into a group photograph and combining clothing, shoes, bags, and other items for virtual try-on.
For more information, see the official Qwen-Image 2.1 announcement.
Links
- Qwen-Image 2.1: Official announcement and model information
- Qwen-Image 2.1 GGUFs: GGUF models on Hugging Face
- Qwen-Image 2.1 for ComfyUI: Official Comfy-Org models and workflows
- ComfyUI-GGUF: GGUF support for ComfyUI
Why Use GGUF?
The official ComfyUI release includes several versions of Qwen-Image 2.1, including BF16 and INT8 versions.
The BF16 diffusion model is approximately 14 GB, while the official INT8 version is approximately 7.3 GB. That’s before considering the memory required by the text encoder, VAE, and the rest of the ComfyUI workflow.
GGUF provides another way to reduce the memory requirements.
The RealRebelAI release currently provides Q2, Q3, Q4, Q5, Q6, and Q8 versions. Importantly, these aren’t simply generic GGUF conversions.
The author created a Qwen-Image-2.1-specific mixed-precision quantization scheme. Some of the more sensitive layers remain at higher precision to reduce the quality loss normally associated with aggressive quantization.
This makes the GGUF versions more interesting than a straightforward low-bit conversion.
Which Qwen-Image 2.1 GGUF Should You Use?
The available quantizations include:
| Model | Base Quantization | Quality | Memory |
|---|---|---|---|
| Q2_K-HQv3 | Q2_K | Lowest | Lowest |
| Q3_K_M-HQv3 | Q3_K_M | Low | Low |
| Q4_K_M-HQv3 | Q4_K_M | Good | Moderate |
| Q5_K_M-HQv3 | Q5_K_M | Very Good | Higher |
| Q6_K-HQv3 | Q6_K | Excellent | Higher |
| Q8_0-HQv3 | Q8_0 | Highest | Highest |
For most users, the Q4_K_M-HQv3 version is the recommended starting point.
If you have additional VRAM available, Q5, Q6, or Q8 should provide additional precision. The Q2 and Q3 versions are primarily intended for systems where memory is the limiting factor.
Keep in mind that lower quantization can affect fine details, anatomy, typography, prompt adherence, editing fidelity, and texture consistency.
What You Need
You will need:
- A recent version of ComfyUI with Qwen-Image 2.1 support
- ComfyUI-GGUF
- A Qwen-Image 2.1 GGUF diffusion model
- The Qwen3-VL 8B text encoder
- The Qwen-Image 2.1 VAE
- A Qwen-Image 2.1 ComfyUI workflow
Qwen-Image 2.1 is supported natively by current ComfyUI, so you don’t need a separate custom node specifically for Qwen-Image 2.1.
However, GGUF loading requires ComfyUI-GGUF.
Step 1: Install or Update ComfyUI-GGUF
If you already use GGUF models in ComfyUI, you may already have ComfyUI-GGUF installed.
Make sure it is updated to a version that supports Qwen-Image 2.1.
You can install it through ComfyUI Manager, or manually clone the repository into your custom_nodes directory.
For a portable Windows installation, the directory will look something like this:
ComfyUI_windows_portable/
└── ComfyUI/
    └── custom_nodes/
        └── ComfyUI-GGUF/
If you already have ComfyUI-GGUF installed, update the existing installation instead of cloning another copy.
Step 2: Download the Qwen-Image 2.1 GGUF
Download the GGUF from the RealRebelAI repository:
Qwen-Image 2.1 GGUFs
For a good balance between quality and memory usage, I recommend starting with:
Qwen-Image-2.1-Q4.gguf
Place the file in:
ComfyUI/
└── models/
    └── diffusion_models/
        └── Qwen-Image-2.1-Q4.gguf
The exact filename may change as additional versions are uploaded, so check the repository for the current files.
Step 3: Download the Text Encoder
The GGUF file is only the diffusion model.
You still need a Qwen-Image 2.1 text encoder.
The official Comfy-Org repository currently provides several Qwen3-VL 8B versions:
qwen3vl_8b_bf16.safetensors
qwen3vl_8b_int8_convrot.safetensors
qwen3vl_8b_w4a8.safetensors
Place the selected text encoder in:
ComfyUI/
└── models/
    └── text_encoders/
        └── qwen3vl_8b_....safetensors
If VRAM is limited, the lower-memory text encoder options can be useful.
The important thing to understand is that quantizing the diffusion model does not automatically quantize the text encoder. They are separate components.
Step 4: Download the VAE
You also need the Qwen-Image 2.1 VAE.
The official Comfy-Org package provides:
qwen_image_2.1_vae_bf16.safetensors
Put it in:
ComfyUI/
└── models/
    └── vae/
        └── qwen_image_2.1_vae_bf16.safetensors
Your final model directories should look roughly like this:
ComfyUI/
└── models/
    ├── unet/
    │   └── Qwen-Image-2.1-Q4.gguf
    │
    ├── text_encoders/
    │   └── qwen3vl_8b_....safetensors
    │
    └── vae/
        └── qwen_image_2.1_vae_bf16.safetensors
Step 5: Load the GGUF Workflow
The official ComfyUI Qwen-Image 2.1 package provides workflows for both:
- Text-to-image
- Image editing
You can also use the workflow supplied with the RealRebelAI GGUF repository.
The important difference from the normal Qwen-Image workflow is the model loader.
Instead of loading the standard .safetensors diffusion model, use the GGUF diffusion/UNet loader provided by ComfyUI-GGUF.
Select:
Qwen-Image-2.1-Q4.gguf
The rest of the workflow still uses the normal Qwen-Image 2.1 components.
In other words:
Prompt
   ↓
Qwen3-VL Text Encoder
   ↓
Qwen-Image 2.1 GGUF
   ↓
VAE
   ↓
Image
The GGUF file replaces the diffusion model. It does not replace the text encoder or VAE.
Step 6: Generate an Image
Once everything is loaded, enter a prompt and queue the workflow.
For example:
A realistic portrait of a young woman standing on a quiet
European street in the early morning, soft natural light,
detailed skin texture, subtle imperfections, realistic
photography, shallow depth of field
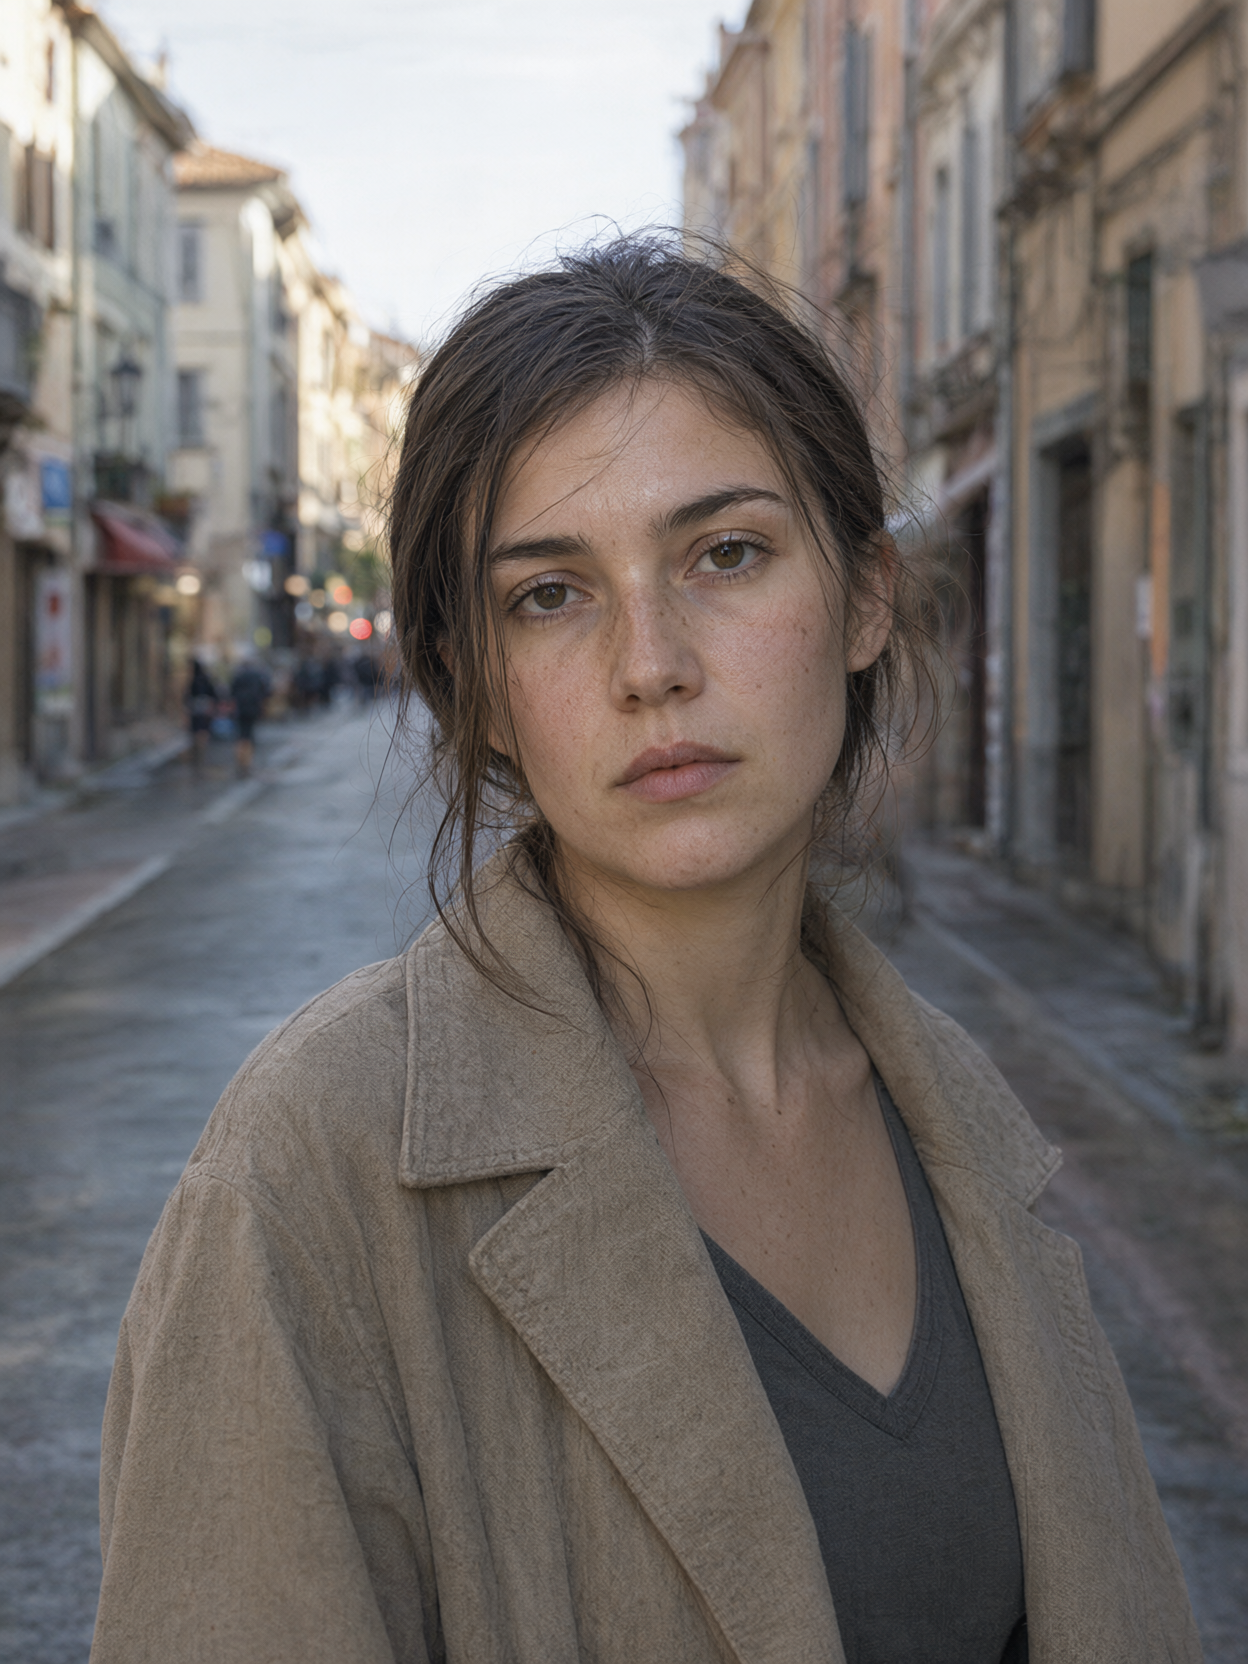
Qwen-Image 2.1 is particularly interesting for prompts that contain detailed instructions or text because Qwen has specifically improved typography and layout.
You can also experiment with more complex prompts involving multiple subjects and objects.
Qwen-Image 2.1 Image Editing
One of the biggest reasons to try Qwen-Image 2.1 is that generation and editing are handled by the same model.
You can load an image into the editing workflow and describe the desired change.
For example:
Change the woman's jacket to a black leather jacket.
Keep her face, hairstyle, pose, lighting, and background unchanged.
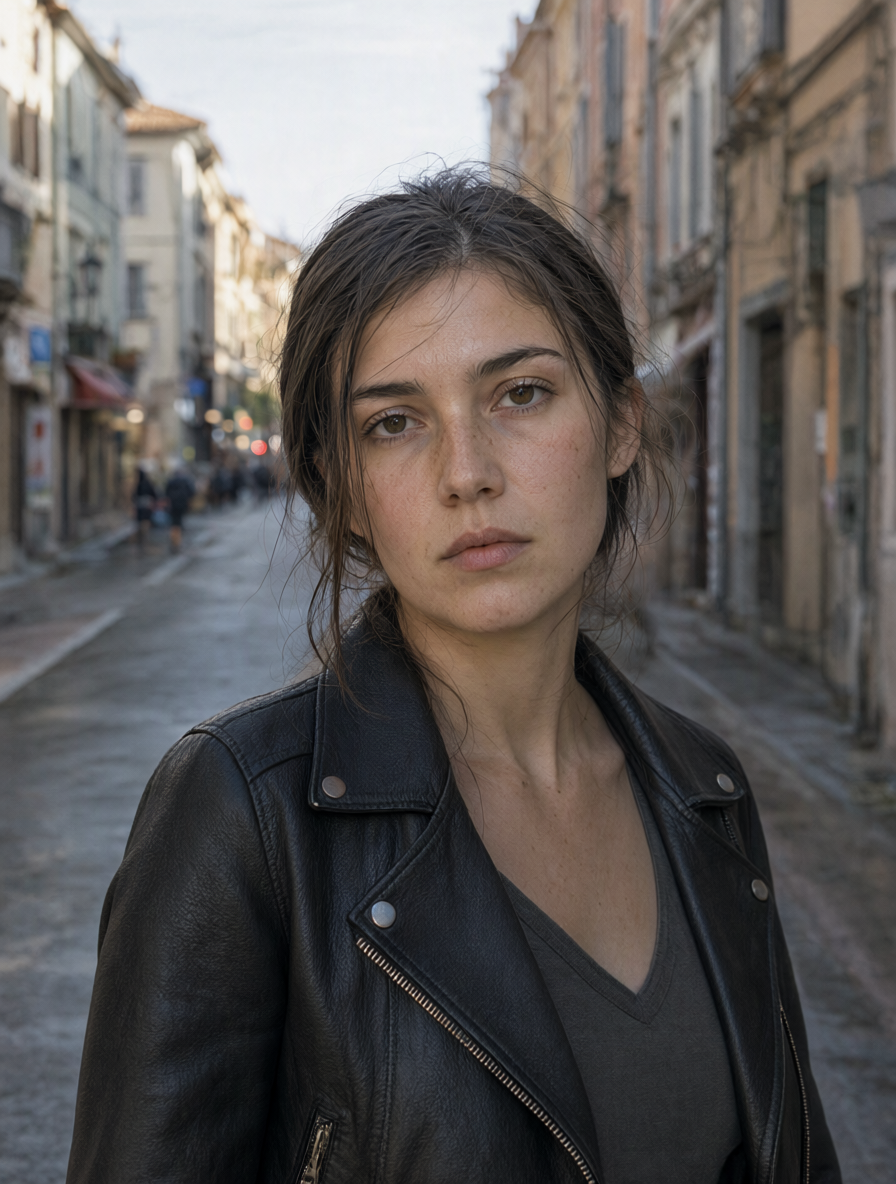
The model also supports more localized editing using masks and visual annotations.
This makes it possible to tell the model not only what to change, but also where the change should happen.
Qwen-Image 2.1 can accept up to 10 reference images, which opens up considerably more complicated workflows than a traditional single-image img2img setup.
Native Transparency
Another new feature in Qwen-Image 2.1 is native transparency.
The model can generate images with transparent backgrounds rather than requiring a separate background-removal step.
It can also edit transparent images while preserving the transparent background.
This is particularly useful for:
- Product images
- Character assets
- Logos and graphics
- Game assets
- E-commerce images
- Compositing
- Sticker-style images
Qwen also demonstrates extracting a subject from a photograph and producing an RGBA layer with transparency.
Q4 vs Q5 vs Q6 vs Q8
If you have enough VRAM, it can be tempting to simply use the largest GGUF.
However, the practical choice depends on your hardware and what you are doing.
For ordinary text-to-image generation, Q4 is a sensible starting point.
If you notice problems with:
- Fine details
- Hands
- Faces
- Typography
- Texture
- Prompt adherence
try moving to Q5 or Q6.
If memory isn’t a concern and you want to stay as close as possible to the higher-precision model, Q8 is another option.
The advantage of the GGUF release is that you can move between these versions without changing the overall ComfyUI workflow.
GGUF vs the Official INT8 Model
Qwen-Image 2.1 also has an official INT8 diffusion model.
So why use GGUF?
The main advantage is flexibility.
The official INT8 model provides a relatively high-precision option, while the GGUF release gives you several quantization levels.
For example:
Q4 → lower memory
Q5 → higher quality
Q6 → even higher precision
Q8 → close to full precision
The RealRebelAI GGUFs also use a mixed-precision strategy specifically designed for Qwen-Image 2.1.
That is important because a generic Q4 conversion can produce more visible quality loss than a carefully designed mixed-precision conversion.
Troubleshooting
The GGUF model doesn’t appear in ComfyUI
Make sure the file is in:
ComfyUI/models/unet/
Then restart ComfyUI.
Also make sure ComfyUI-GGUF is installed and updated.
The workflow says the model is missing
Check the model filename selected in the GGUF loader.
You may have downloaded a different quantization than the workflow expects.
For example, the workflow may be configured for:
Qwen-Image-2.1-Q4.gguf
while you downloaded:
Qwen-Image-2.1-Q6.gguf
Simply select the correct file in the loader.
The text encoder is missing
Remember that the GGUF only contains the diffusion model.
You still need a Qwen3-VL 8B text encoder in:
ComfyUI/models/text_encoders/
The VAE is missing
Download the Qwen-Image 2.1 VAE and put it in:
ComfyUI/models/vae/
The image quality isn’t what you expected
Try a higher quantization level.
Qwen-Image 2.1 GGUFs can still lose some quality at lower bit depths, particularly in fine details, anatomy, typography, and texture consistency.
Going from Q4 to Q5 or Q6 is worth trying before changing the entire workflow.
Final Thoughts
Qwen-Image 2.1 is an interesting release because it combines image generation, editing, transparency, and multi-image reference workflows in a relatively compact 7B visual generation model.
For ComfyUI users, the new GGUF versions make it easier to experiment with the model without committing to the memory requirements of the full BF16 checkpoint.
I’d start with Q4 and move up to Q5, Q6, or Q8 if your hardware allows it.
The most important thing to remember is that the GGUF is only the diffusion model. You still need the Qwen3-VL text encoder, Qwen-Image 2.1 VAE, and the appropriate ComfyUI workflow.
Once those pieces are installed, Qwen-Image 2.1 can be used just like the other modern image models in ComfyUI—while giving you a surprisingly broad set of generation and editing capabilities.
Leave a Reply