The Hunyuan Video AI model is a cutting-edge text-to-video generation tool developed by Tencent’s Hunyuan AI team. Designed to transform textual prompts into high-quality video […]
When working with LTX Video’s image-to-video generation, creators often face two key challenges. First, captions for input images can be inconsistent or unclear, leading to […]
LTX Video is an innovative tool by Lightricks that brings the power of AI video generation directly to your local machine. Designed to integrate seamlessly […]
As mentioned in the previous blog post, Stable Diffusion 3.5 Medium is released. Stable Diffusion 3.5 Medium is a Multimodal Diffusion Transformer with improvements (MMDiT-X) text-to-image […]
LoRA (Low-Rank Adaptation) is a technique used in Stable Diffusion to fine-tune models efficiently without requiring extensive computational resources. It allows users to adapt a […]
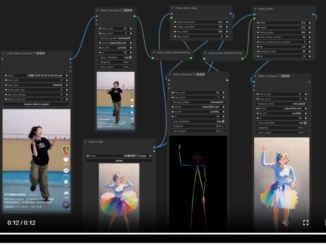
According to the MusePose readme on github: MusePose is an image-to-video generation framework for virtual human under control signal such as pose. The current released model […]